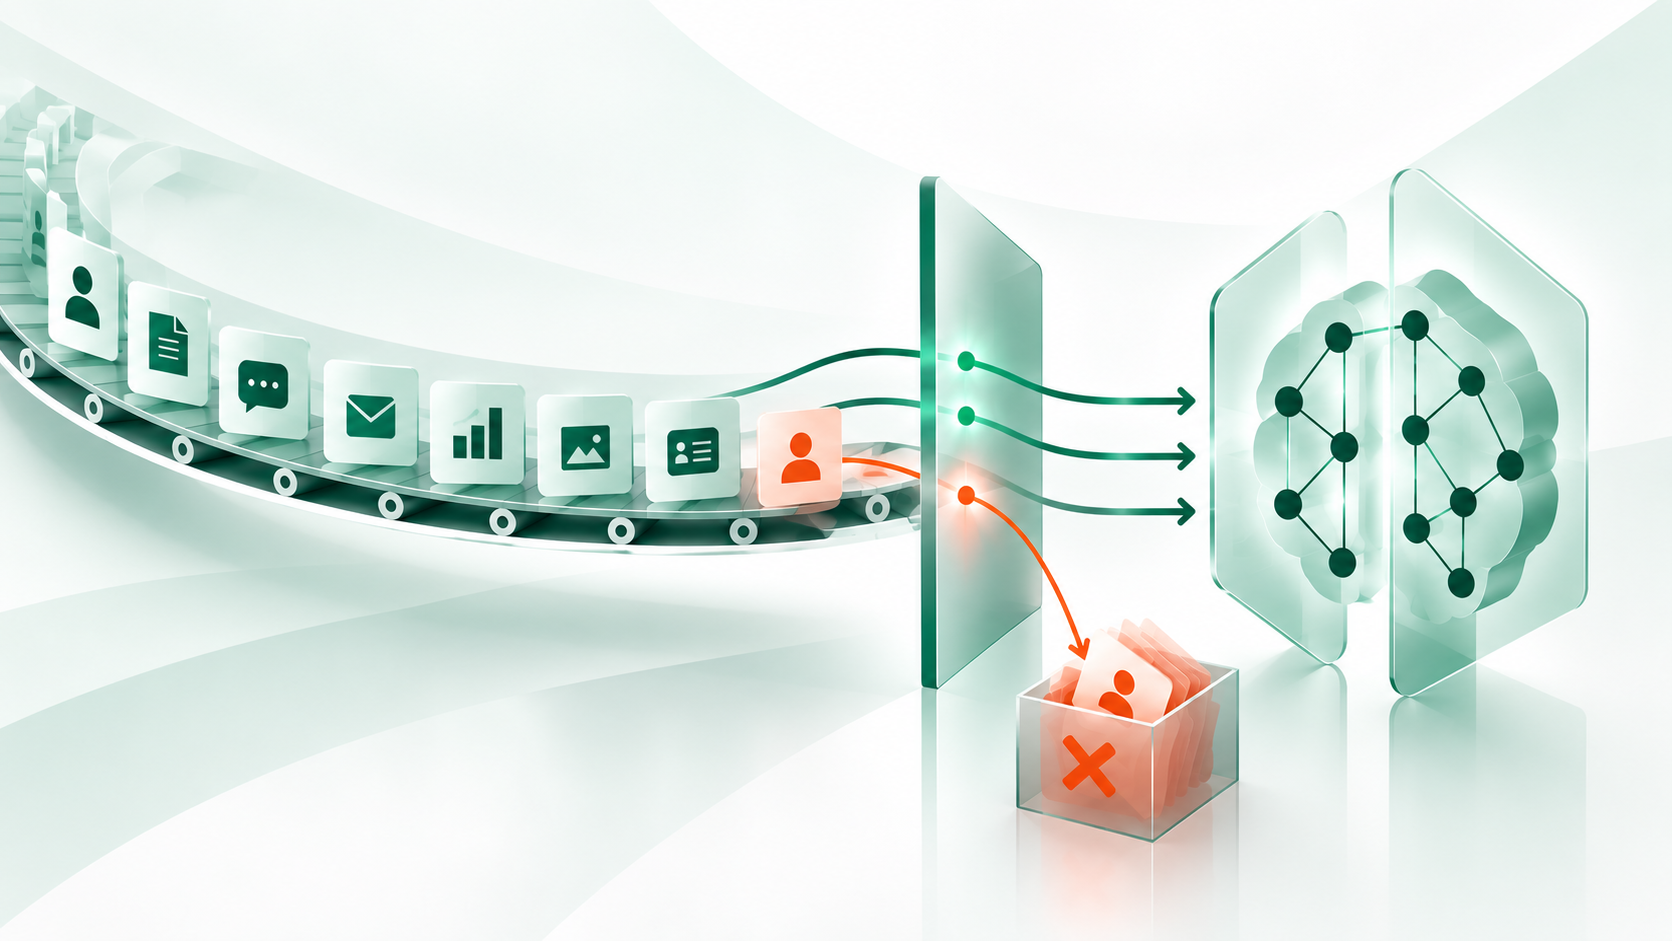
Data Protection in AI Systems: Transparency, Accountability and Secure Data Processing
A company integrates a chatbot into its customer service operation. The legal department asks about the data processing agreement, while IT has already enabled access. This sequence is common — and it can already result in a violation. As soon as the first customer inquiry reaches the provider, the provider is processing personal data. This processing requires an agreement pursuant to Article 28(3) of the General Data Protection Regulation (GDPR). The GDPR does not distinguish between a system being piloted and being operated in production. It asks whether personal data is being processed.
The Role Your Company Actually Takes
Every AI project starts with the question of who is responsible for the processing. Three scenarios are particularly common in practice.
If a company develops and uses a model entirely on its own, it is the sole controller. If it uses an AI-as-a-Service offering and the provider uses the prompts generated to improve its model for all customers, this will generally result in joint controllership under Article 26 GDPR, because the provider is pursuing its own interests. If a service provider trains a model strictly according to instructions and does not pursue its own purposes, this constitutes processing on behalf of a controller.
The role can change within the same project. A provider that initially acts solely as a processor becomes a joint controller as soon as it uses customer data across tenants for its own model training. If this is not clarified when the contract is concluded, the issue often only becomes apparent when the provider next updates its terms of use.
Legal Basis: Consent Is Rarely the Only Answer
When training proprietary models using existing datasets, legitimate interest under Article 6(1)(f) GDPR is generally the legal basis used in practice, rather than consent. The reason is straightforward: in cases such as web scraping or the use of existing customer data, obtaining valid and informed consent is often no longer realistically possible.
In Opinion 28/2024, the European Data Protection Board (EDPB) developed a three-step test for this purpose. There must be a legitimate interest, the processing must be necessary for that purpose, and the interests of the data subjects must not override the legitimate interest.
A recent case illustrates how robust this approach can be. In May 2025, the Higher Regional Court of Cologne (OLG Köln) rejected an application by the North Rhine-Westphalia Consumer Advice Centre concerning Meta's AI training using publicly accessible Facebook and Instagram posts. The court found no less intrusive means of achieving the training purpose and concluded that the balancing of interests favoured Meta, also taking into account that users had been informed in advance and had the opportunity to object.
For companies applying this approach in practice, the implication is clear: anyone relying on legitimate interest must actually carry out and document all three steps of the assessment rather than merely asserting that they have been met.
Data Subject Requests That No One Can Fully Answer
One aspect is regularly underestimated in AI projects. When a data subject requests access to, deletion of, or rectification of their data in an already trained language model, the company encounters a technical limitation. Within the model parameters of a Large Language Model (LLM), an individual data point cannot generally be identified or removed in isolation without changing the model's overall behaviour.
The response relies on the disproportionate effort provision under Article 12(5) GDPR: the company rejects the access or deletion request on technical grounds and undertakes to remove the relevant data from the training data during the next training cycle.
However, this does not apply equally to all three scenarios. If the training data originates from an external provider, the company using the model may only be able to state that it does not have the requested information and must forward the request. If the company compiled the training data itself, it must actually be able to provide information and make corrections to the underlying dataset.
For ongoing user inputs (prompts), the normal GDPR regime applies: the company must document deletion and retention requirements and implement deletion once the relevant retention period has expired. This distinction should be explicitly addressed in any internal policy governing data subject requests.
Effective Measures Instead of Statements of Principle
Four technical and organisational measures provide the greatest practical impact.
1) A prompt filter placed upstream reduces the amount of personal data entered before it reaches the system in the first place. It does not replace training, but it makes training more effective by catching errors that still occur despite training.
2) Companies should contractually exclude the use of inputs to an AI tool for further model training by the provider. Many providers offer a technical opt-out setting for this purpose. However, this can often only be configured at user level rather than centrally. If it is not configured centrally, purpose limitation ultimately depends on individual behaviour.
3) Pseudonymised user accounts and a documented deletion concept for interaction logs are essential as soon as a chatbot or internal tool stores user inquiries over an extended period.
4) An access control concept for AI systems is just as fundamental as the established record of processing activities, which should be expanded to include the AI applications being used.
When a Data Protection Impact Assessment Becomes Mandatory
Anyone who systematically and comprehensively evaluates personal aspects — for example, through automated decision-making in recruitment or creditworthiness assessments — must carry out a Data Protection Impact Assessment (DPIA) under Article 35 GDPR.
The same obligation arises as soon as an AI system processes special categories of personal data under Article 9 GDPR. This applies to AI systems more directly than might initially appear: biometric identification, AI-assisted medical diagnostics, and HR scoring tools that infer health or ethnic origin from application documents all involve or generate data falling into this category.
In practice, DPIAs are often only carried out retrospectively, once the system is already in use. Legally, this is too late and becomes apparent in the documentation. The DPIA belongs before the rollout, not afterwards, and should be coordinated with the Fundamental Rights Impact Assessment under Article 27 of the AI Act where this is additionally required.
Conclusion
Most data protection issues in AI projects do not arise from a lack of awareness, but from getting the sequence wrong. Responsibility, legal basis and technical measures need to be addressed before implementation, not as part of the follow-up process.
Companies that clarify their role in advance and understand the limitations surrounding data subject requests relating to already trained models do not have to improvise when a request arises. Instead, they can refer to a documented assessment.
If you need support with the data protection-compliant implementation of AI systems, please feel free to contact us.